
You have a long text file open and a small problem hiding somewhere inside it. Maybe a list of customer notes contains order codes. Maybe a server log mixes dates, emails, and status messages. Maybe a spreadsheet export has the same mistake repeated on hundreds of lines. Scanning line by line works for the first minute, then your attention starts skipping.
Regular expressions, usually shortened to regex, are a way to describe the text you want to find. A regex can search for one exact word, but it can also search for a shape: three letters followed by four numbers, a line that starts with an invoice id, or every repeated space before a comma. BlinkCalc's Regex Tester gives you a safe place to try those patterns against sample text before you trust them in code, an editor, or a data cleanup step.
What regex is
A regex is a compact search pattern. Instead of saying "find the word paid", you can say "find paid at the start of a line", "find paid only when it appears after status:", or "find paid, pending, or failed". The pattern becomes a small language for describing text.
That language can look sharp at first because punctuation has meaning. A dot can stand for a character you have not pinned down. Square brackets can mean a set of allowed characters. Parentheses can capture part of a match. The trick is not to memorize the entire language at once. Start with exact text, add one idea at a time, and test the result on examples that look like your real data.
Regex is useful in code editors, log searches, form validation, data cleanup, analytics exports, command-line tools, and programming languages. It is especially good when the text has a repeated structure. It is less pleasant when the text is ambiguous or when a full parser would understand the format better.
Literal characters
The simplest regex is ordinary text. The pattern error finds the letters e-r-r-o-r in that order. The pattern INV-2048 finds that exact invoice code. These are called literal characters because they mean themselves.
Literal matching is already useful. In a support export, you might search for refund requested. In a log, you might search for timeout. In a list of product SKUs, you might search for BAG-XL. Many practical regex jobs begin as literal searches and become patterns only when the exact value changes from line to line.
Some characters are special in regex, including ., *, +, ?, (, ), [, ], {, }, ^, $, |, and \. If you want one of those to mean the actual character, escape it with a backslash. For example, 3\.5 matches 3.5, while 3.5 can match 315, 3a5, or 3-5 because the dot is special.
The dot is worth one extra note. In most engines it matches any character except a line break, and only matches line breaks when a dotall or single-line flag is turned on. So a dot is broad, but it is not automatically "every character in every mode".
Patterns instead of exact text
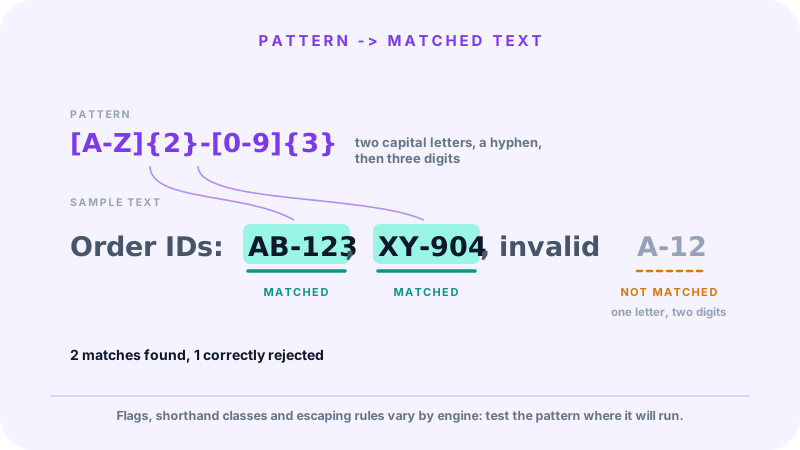
Pattern matching begins when one part of the text can vary. A customer code might look like AB-4921, CD-1038, and XZ-8870. You do not want one search for every code. You want a pattern for the shape.
A beginner-friendly version is [A-Z][A-Z]-[0-9][0-9][0-9][0-9]. It says: uppercase letter, uppercase letter, hyphen, digit, digit, digit, digit. It is longer than the examples, but the meaning is visible. Once that works, you can shorten the repeated pieces with quantifiers.
The pattern [A-Z]{2}-[0-9]{4} says the same thing in a more compact way. Two uppercase letters, a hyphen, and four digits. The goal is not to create the cleverest possible regex. The goal is to create the clearest pattern that matches what you mean and rejects obvious wrong cases.
Character classes
A character class is a set of characters that can appear in one position. [aeiou] matches one lowercase vowel. [0-9] matches one digit. [A-Z] matches one uppercase English letter. [A-Za-z] matches one uppercase or lowercase English letter.
Character classes are the first big step away from literal searching. They let you write flexible patterns without opening the door to everything. For example, file[0-9] matches file1 and file7, but not fileA. v[12] matches v1 and v2, but not v3.
There are shorthand classes too. In many regex engines, \d means digit, \w means word character, and \s means whitespace. These are convenient, but their exact meaning varies by engine and settings. In Python 3, \d and \w match Unicode digits and letters by default, so Arabic-Indic or Devanagari digits count. In JavaScript, \d is always ASCII [0-9], and matching wider Unicode ranges needs property escapes such as \p{Nd} with the u or v flag. If your text is not plain English, check what the shorthand means in your engine before trusting it. When teaching or debugging, [0-9] and [A-Za-z] are sometimes easier to read than shorthand.
Quantifiers
Quantifiers say how many times the previous item may repeat. The star * means zero or more. The plus + means one or more. The question mark ? means optional. Curly braces give exact or ranged counts.
Here are useful examples:
| Pattern | Meaning | Example match |
|---|---|---|
[0-9]+ | one or more digits | 48125 |
[A-Z]{3} | exactly three uppercase letters | SKU |
colou?r | optional u | color, colour |
[a-z]{2,5} | two to five lowercase letters | code |
Quantifiers are greedy by default: each one takes as much text as it can while still letting the rest of the pattern match. Most engines also support a lazy form written with a trailing ?, such as .*?, which takes as little as possible. Lazy quantifiers change where a match stops, but they are not a substitute for a narrower pattern.
Quantifiers are powerful because they reduce repetition. They are also where many mistakes begin. .* means any character, zero or more times, and can swallow more text than expected. A precise class such as [0-9]+ or [^,]+ is often safer than a broad dot-star pattern.
Anchors
Anchors match positions rather than characters. ^ matches at the start of the input and $ at the end. The important detail is what "the input" means. In most programming-language engines, those anchors apply to the whole string by default, and only match at each line break when multiline mode is enabled. Line-oriented tools such as grep test one line at a time, so ^ERROR already behaves per line there. In a regex tester, check the multiline flag before assuming ^ERROR finds every line that begins with ERROR. The pattern \.pdf$ finds text that ends with .pdf.
Anchors are useful when the same word appears in different places. Suppose a file contains:
status: paid
note: customer said paid already
status: pending
The pattern paid finds both the status and the note. With multiline mode on, the pattern ^status: paid$ finds only a whole line that exactly says status: paid; without it, the same pattern only matches when that text is the entire input. That extra precision matters when you are replacing text, filtering rows, or searching logs where a casual match could include the wrong record.
Groups
Parentheses group part of a pattern. They can make alternatives clearer and can capture useful pieces. The pattern (paid|pending|failed) matches one of three status words. The pattern Order ([0-9]+) can match Order 4812 and capture 4812 separately.
Capture groups help when you want to extract part of the text rather than merely find the whole match. A list might contain User: maya@example.test. A pattern such as User: ([^ ]+) can capture the email-like value after the label.
Groups can also become confusing if there are too many of them. For beginner patterns, use groups only where they add obvious value. If a group is just for structure and you do not need to capture it, most engines, including JavaScript, Python, PCRE, Java, and .NET, support non-capturing groups like (?:paid|pending). That is useful later, but not required for a first pass.
A messy text example
Imagine this short export:
Order AB-4921  maya@example.test   paid
Order CD-1038  no-email            pending
Order XZ-8870  rafi@example.test   failed
note: refund for order CD-1038
Order Q7-1000  broken@example      paid
You might want all order ids that follow two letters, a hyphen, and four digits. [A-Z]{2}-[0-9]{4} matches AB-4921, CD-1038, and XZ-8870. It does not match Q7-1000 because the second character is a digit, not a letter. That is a useful rejection.
You might want email-like values for a quick cleanup pass. A beginner pattern such as [A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,} catches maya@example.test and rafi@example.test. It is not a perfect email validator, but it is practical for finding likely email addresses in text.
You might notice uneven spacing. Before testing a pattern, the Remove Extra Spaces tool can make copied text easier to read. After extracting lines, Sort Text Lines can group similar records so repeated formats stand out.
Why testing regex matters
Regex mistakes can be quiet. A pattern may match too little, too much, or the right text for the wrong reason. If you use that pattern in a search-and-replace operation, a log filter, or a validation rule, the mistake can spread quickly.
Testing gives you three checks. First, does the pattern match examples that should pass? Second, does it reject examples that should fail? Third, does it behave well around edge cases such as blank lines, punctuation, repeated spaces, and similar-looking values?
Use real-looking sample text, but remove sensitive information. Replace customer emails, tokens, addresses, or internal URLs with fake equivalents. Regex testing does not require production data to prove the pattern shape.
How to use the Regex Tester
Open the Regex Tester, paste a small sample into the text area, and enter the pattern without the surrounding slashes unless the tool asks for them. Start with a literal piece, confirm it matches, then add classes, quantifiers, anchors, or groups.
Turn flags on only when you need them. The global flag finds multiple matches. The case-insensitive flag treats Error and error alike. Multiline mode changes how start and end anchors behave around line breaks. Flags are not decorations; they change the meaning of the result.
Read the matches, not just the match count. A count of 18 is not helpful if four of those matches are accidental. Look at the highlighted text, compare it with your intent, and add a few fail cases to the sample. When the pattern is ready, copy it into your editor or code and test again in the final environment.
When companion text tools help
Regex rarely lives alone. If you are comparing the output of a regex replacement before and after a change, Text Diff Checker can show exactly what changed. That is handy when removing prefixes, standardizing codes, or cleaning exported text.
If the sample text has inconsistent whitespace, normalize a copy with Remove Extra Spaces before writing the pattern. Do not assume the production text is clean, but a cleaned sample can help you understand the target shape.
When matches are line-based, Sort Text Lines can bring similar records together. Sorting logs, ids, or copied rows often reveals that you actually have two formats, not one.
Replacements and extraction
Finding text is only half of many regex jobs. The next step is often replacing or extracting. In a code editor, you might turn Last, First into First Last. In a log cleanup, you might extract only the request ids. In a spreadsheet prep step, you might remove a repeated prefix from every line.
Capture groups make this possible. If a line says Name: Patel, Mira, the pattern Name: ([A-Za-z]+), ([A-Za-z]+) can capture the last name and first name separately. A replacement pattern in many tools can then rearrange those groups. The exact replacement syntax varies by tool, so test it in the environment where you will run it.
For extraction work, save a small sample of expected matches. Include a normal line, a line with extra spacing, a line that should fail, and a line with punctuation. If the pattern survives that small set, you have more confidence before running it on the whole file.
A safer regex workflow
A reliable regex workflow is slow for the first five minutes and fast afterward. First, write down the format in plain language. "Two uppercase letters, a hyphen, four digits" is clearer than jumping directly to symbols. Second, create pass and fail examples. Third, build the pattern in small steps.
Fourth, test with realistic boundaries. If you are matching a code in a sentence, do not test only the code by itself. Put it before commas, after labels, inside longer text, and on blank lines. Fifth, use the least broad pattern that works. A specific class usually ages better than a catch-all.
Finally, keep the pattern readable. A slightly longer regex with obvious parts is often better than a compressed pattern nobody wants to maintain. Future you may be the person debugging it.
Common mistakes
The first mistake is using .* too early. It works in quick demos, then grabs half a line or crosses boundaries you did not expect. Prefer a specific class when you can. For comma-separated text, [^,]+ is usually more controlled than .*.
The second mistake is forgetting to escape literal dots. A file pattern like .pdf can match apdf because the dot means any character. Use \.pdf when you mean the actual extension.
The third mistake is testing only happy paths. A pattern for order ids should include broken ids, lowercase ids, missing hyphens, and extra digits in the sample. Rejections teach you as much as matches.
The fourth mistake is assuming every regex engine behaves exactly the same. JavaScript, Python, PCRE, Java, .NET, RE2, and database engines all differ. Lookbehind, named groups, backreferences, and Unicode property escapes are the usual sticking points: JavaScript only gained lookbehind and named capture groups in ES2018, and RE2, used by Go's standard regexp package and several Google tools, leaves out backreferences and lookaround on purpose so that matching time stays predictable. Test in the engine you will use.
The fifth mistake is solving every text problem with regex. Nested formats such as HTML, XML, JSON, and programming languages need parsers, because nesting can go arbitrarily deep and a classic regex has no way to count how deep it is. Regex is excellent for patterns; it is not a full understanding of every format.
FAQ
What is a regex tester used for?
A regex tester lets you try a regular expression against sample text and inspect the matches before using it elsewhere. It is useful for learning syntax, debugging a pattern, checking capture groups, and avoiding risky replacements.
Is regex the same in every programming language?
No. The broad ideas are similar, but details vary. Flags, lookarounds, Unicode behavior, named groups, backreferences, and escaping rules can differ. Some engines, such as RE2, deliberately omit backreferences and lookaround to guarantee predictable performance. A pattern tested in one tool should still be checked in the language or platform where it will run.
What is the easiest regex pattern to start with?
Start with literal text, then add one flexible part. For example, search for Order, then Order [0-9]+, then anchor it if needed. Building in small steps is easier than writing a full pattern from memory.
Why does my regex match too much text?
Broad patterns and greedy quantifiers are common causes. .* will often match more than expected. Replace it with a narrower class, add an anchor, or test shorter examples to see where the pattern starts and stops.
Can regex validate every email address perfectly?
Not comfortably. Email rules are more complicated than most people need for everyday cleanup. Use regex to find likely email-like text, but rely on application validation and confirmation workflows for serious account or delivery checks.
Should I use regex for parsing HTML?
For small searches, such as finding a specific attribute in a controlled snippet, regex may be okay. For real HTML parsing, use an HTML parser, and for JSON use a JSON parser. Both formats nest to arbitrary depth, contain quoted text, and vary in ways regex handles poorly.